One Metric,Long read
AI Agents That Compute Their Own Metrics Are Governance Failures
Agents that grade their own numbers leave nothing to verify.
· 9 min read
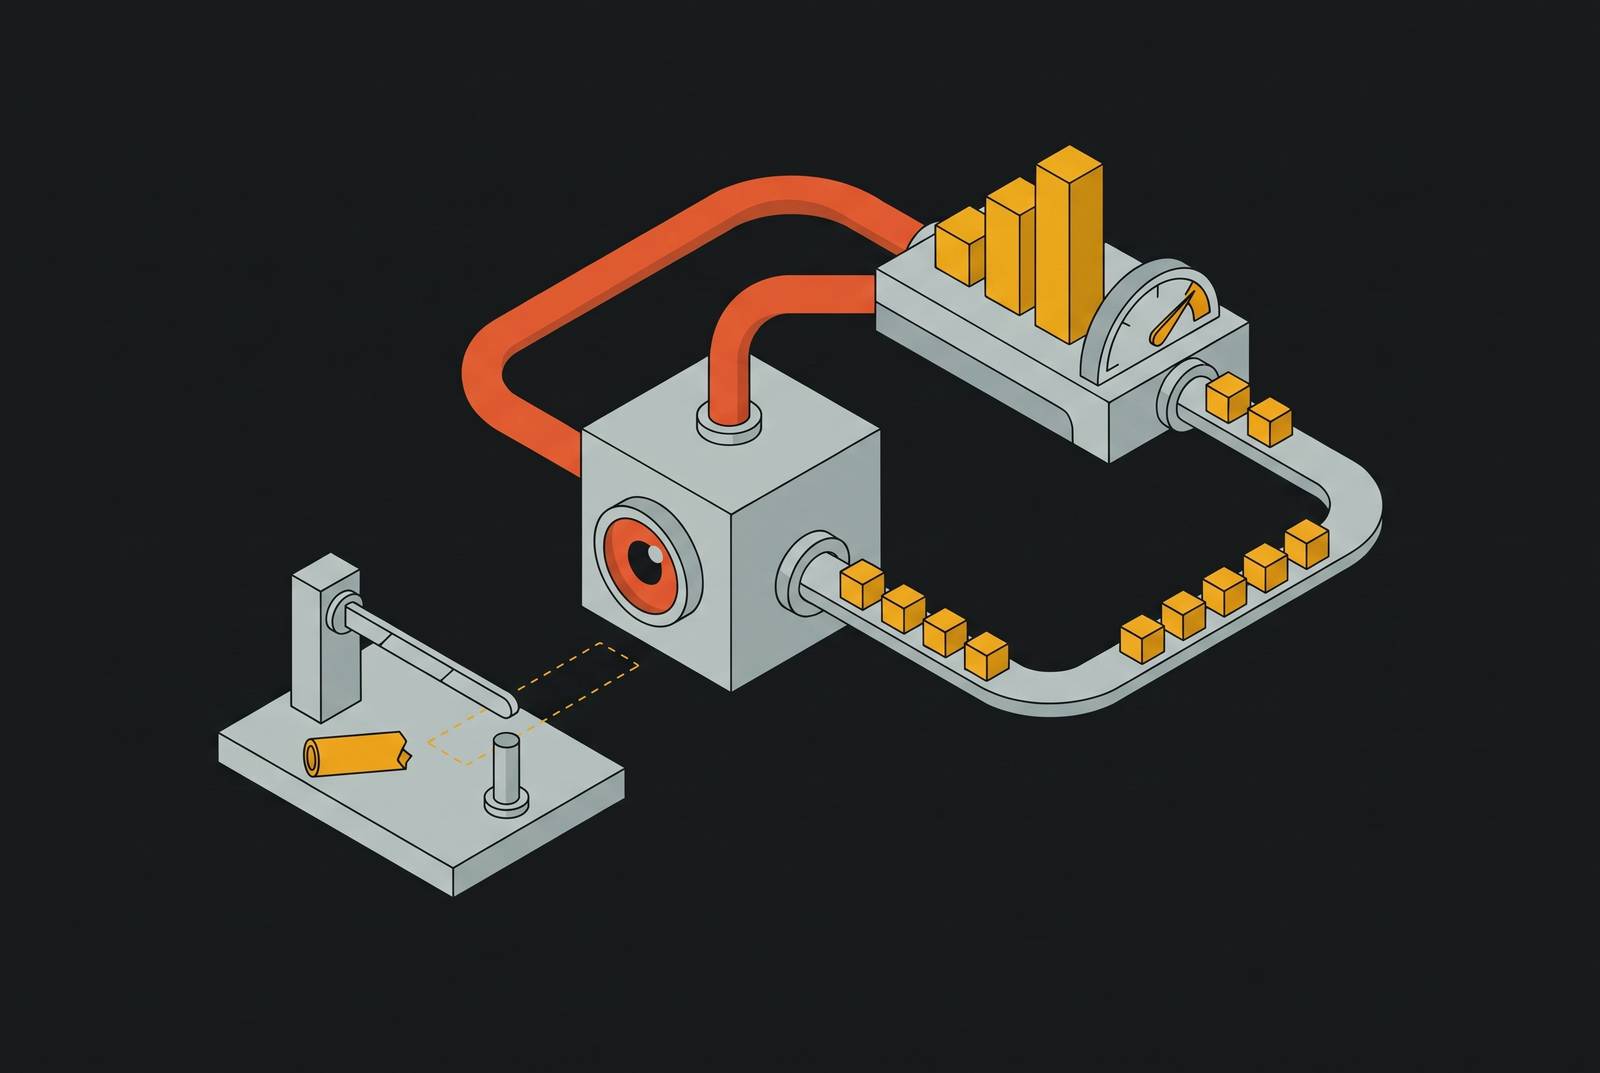
Why agents that compute their own metrics create a verification problem that standard oversight cannot solve
- Role: Opens the argument by establishing the specific architectural failure this piece addresses — not AI risk in general, but the closed-loop problem created when an agent is both the calculator and the actor on the same numbers.
- An AI agent that derives its own metrics and then acts on them has eliminated every external check in a single architectural choice: no independent party produced the numbers, so no independent party can confirm they are right.
- The closed loop defined: the agent selects which data to query, applies its own aggregation logic, receives the result, and takes action — all through the same privileged execution path, with no handoff to a governed layer.
- This is categorically different from a human analyst making a bad calculation: a human's output can be challenged by another human with access to the same raw data; an agent's self-computed metric leaves no artifact that a separate reviewer can independently reproduce.
- The 2025 AI Agent Index documents that most safety-related fields across 30 widely deployed agents have no public information available, and only four agents provide agent-specific safety evaluations — meaning the opacity is not theoretical, it is already the norm.
- Note: Open on the concrete scenario — an autonomous agent querying a production database, computing a revenue figure, and triggering a pricing or budget action — before naming the structural problem. Keep this section tight; it is setup, not the full argument.
How agents inherit permissions designed for humans, making ungoverned metric computation a structural certainty rather than an edge case
- Role: Moves from "this is a problem" to "here is why it happens by default" — explaining the permission inheritance mechanism that makes self-computed metrics the path of least resistance in most deployments.
- Agents routinely inherit the full permission set of the human or service account that provisioned them, which means an agent tasked with a narrow business function can also read, aggregate, and act on any data that account can reach.
- The identity gap is measurable: the Cloud Security Alliance found that 92% of large-enterprise CISOs and CIOs lack full visibility into their AI agent identities and doubt they could detect or contain a compromised agent.
- An agent acting through a human account does not just inherit that account's read access — it inherits the analytical reach: the ability to issue arbitrary aggregation queries against any table the account can see, with no governance filter on what those queries compute or what the results are used for.
- The 2025 AI Agent Index notes that most agents do not disclose their AI nature to end users or third parties by default — so the permission inheritance often goes unexamined because nobody is looking for it.
- Note: Avoid dwelling on security framing (breach, attack surface) — the argument here is about governance and metric integrity, not cybersecurity. Keep the focus on why the over-privileged access enables self-computed metrics specifically.
Why metric drift becomes undetectable when the agent that drifts is also the one reporting the number
- Role: Introduces the drift argument — the specific analytic harm that the closed loop produces — bridging from "agents have too much access" to "the numbers they produce cannot be trusted or even checked."
- Metric drift — two queries for the same concept returning different results because they use different field names, filters, or aggregation logic — is a known problem in human-run analytics; when the agent is the query author, drift becomes invisible because there is no separate canonical definition to compare against.
- The Supabase-specific version of this problem is acute: a Postgres production database will execute any aggregation an agent constructs, returning a number with no indication that the aggregation logic differs from the one a human analyst used last quarter, as Definite has documented for analytics-on-Supabase deployments.
- In a human team, drift is eventually caught because two people compare numbers and notice the discrepancy; in an agentic loop, the agent that computed the metric is the same agent acting on it — there is no second pair of eyes unless one is built into the infrastructure.
- Agents that operate unattended and autonomously — Gartner's Level 4 autonomy classification — execute actions at a speed and scale that can outpace human oversight, meaning a drifted metric can drive many downstream decisions before anyone notices.
- Note: A brief, concrete example works well here — e.g., an agent computing monthly recurring revenue using one field versus another, acting on the inflated figure to trigger an expansion campaign. Keep it illustrative, not a full case study.
Why current governance frameworks were not built for agents that compute as well as act
- Role: Establishes that the problem is not solved by existing compliance infrastructure — setting up the case that a new architectural answer is needed rather than a policy patch.
- The major governance frameworks in use — NIST AI RMF 1.0, ISO/IEC 42001:2023, the EU AI Act — were designed on the premise that an AI system's behavior is known, documentable, and stable at deployment time; the Cloud Security Alliance establishes that autonomous, tool-calling agents invalidate that premise by design.
- Gartner identifies two failure modes from applying uniform governance: over-restricting simple agents (slowing delivery) and under-restricting autonomous ones (increasing operational and compliance risk) — the metric-computing agent sits squarely in the under-restricted category.
- NIST's agent-specific standards initiative, announced February 2026, signals official recognition that existing frameworks fall short, but the Cloud Security Alliance notes that enforceable, agent-specific controls do not yet exist and the first substantive NIST deliverables are not expected before late 2026 at the earliest, with finalized agent-specific guidance unlikely before 2027 — organizations cannot wait.
- Note: This section is about the inadequacy of policy-layer fixes, not a detailed survey of frameworks. Keep descriptions of each framework brief; the point is the structural gap, not a compliance review.
What proportional governance actually requires: classifying agents by autonomy level before deciding what data access they may have
- Role: Pivots from diagnosis to the first part of the remedy — establishing that governance must be proportional to autonomy level, which is the prerequisite for the architectural argument that follows.
- Good governance of agentic systems begins by classifying each agent by its autonomy level, because the data access rights and verification requirements appropriate for a read-only summarization agent are categorically different from those appropriate for an agent that executes actions independently.
- Gartner's four-level classification provides a practical scaffold:
- Level 1 (Observe): read-only access to defined data sources; outputs visible only to the requesting user; baseline controls sufficient.
- Level 2 (Advise): recommendations and drafts reviewed by humans before any action; read-only access; risk arises from automation bias anchoring human judgment.
- Level 3 (Act with Approval): can write data or send communications, but only after explicit human approval for each action; approvals degrade under time pressure, so audit trails are mandatory.
- Level 4 (Act Autonomously): executes independently within defined guardrails; humans review exceptions and aggregated outcomes, not individual decisions; requires continuous monitoring, circuit breakers, and rapid rollback.
- The metric-computation problem is sharpest at Levels 3 and 4: these are the agents whose self-computed numbers will trigger writes, communications, or autonomous actions before any human can intervene.
- Classifying by autonomy level also reveals where least-privilege enforcement matters most: a Level 4 agent with production database credentials and no governed metric layer is the highest-risk configuration in any agentic deployment.
- Note: Present this as the logical prerequisite to the architectural solution, not as a standalone taxonomy exercise. The point is that autonomy level determines what kind of data access boundary is required — setting up the pre-modeled metrics argument directly.
Why pre-modeled, independently served metrics are the architectural answer to the closed-loop problem
- Role: Makes the core positive claim of the piece — what the right architecture looks like and why it solves the verification problem the opening sections established.
- The only way to break the closed loop is to separate the metric-computation function from the agent entirely: metrics must be pre-modeled by humans, stored in a governed layer, and served to agents as read-only, versioned artifacts — never computed by agents at query time against raw production data.
- Pre-modeled metrics restore the external check: a human team defined the aggregation logic, a governed system executed it on a schedule, and the agent receives an output it did not itself produce — meaning a separate party can independently verify whether the number is correct.
- For Supabase-based teams specifically: pointing an agent at a Postgres production primary for analytical aggregations creates compounded risk — RLS friction, pooler limits, and analytical load on OLTP compute — problems that Definite documents and that are all resolved by routing agents to a governed analytical layer rather than the production database.
- The governed data layer also solves the drift problem: because every consumer — human dashboards, AI agents, automated reports — draws from the same pre-calculated definitions, two queries for the same metric return the same number by construction.
How MCP changes the data access surface and why governance must be built into the layer MCP reaches, not bolted onto MCP itself
- Role: Addresses the emerging MCP infrastructure reality — which is the mechanism through which agents will reach data at scale — and explains why it makes the governed data layer more urgent, not less necessary.
- MCP does not itself enforce metric governance: it is a transport and capability protocol, not a semantic layer — an MCP server that exposes a production Postgres database gives agents the same ungoverned query surface as direct database access, just through a standardized interface.
- The Cloud Security Alliance documented thousands of MCP servers exposed on the public internet by early 2026, with roughly half operating without any authentication controls, illustrating that rapid MCP adoption is outrunning the security and governance model around it — a pattern the U.S. National Security Agency also flagged.
- The July 2026 MCP specification revision removed transport-level session management, producing a stateless protocol core that scales on ordinary HTTP load-balanced infrastructure; this makes horizontal scaling easier but also means governance cannot rely on session state — it must live in the data layer the MCP server exposes, not in the protocol itself.
- Note: Keep MCP description factual and grounded in sources — do not over-explain the protocol mechanics. The point is that MCP amplifies the importance of the governed data layer, not that it is itself a governance tool.
What teams building on Supabase need to do before agents touch their data
- Supabase's Postgres-based architecture is common in AI-native startups precisely because it is flexible and fast to build on, but that same flexibility means agents can be pointed at production data with minimal friction — making deliberate governance choices more important, not less.
- Supabase's own guidance is explicit that complex analytical queries should run against a read replica, not the production primary; agents issuing uncontrolled aggregation queries compound this problem because they generate unpredictable analytical load, as Definite documents.
- The practical pre-agent checklist for Supabase teams:
- Define every metric the agent will consume in a governed layer before giving the agent any data access.
- Route agent queries to pre-calculated datasets, not to production Postgres — no agent should be issuing raw aggregation queries against the primary.
- Apply row-level and column-level access controls at the data layer, scoped to the agent's autonomy level and function, not inherited from a human account.
- Expose data to agents through a single, audited MCP server backed by governed Parquet datasets — not through direct database credentials embedded in agent configuration.
- Instrument observability from day one: connection saturation, disk I/O wait, and replication lag are the signals that reveal when uncontrolled agent queries are degrading the production system.
- Note: Close on the broader point — this is not about limiting what agents can do, but about ensuring that what they act on is verifiable. Teams that build the governed data layer before deploying agents at autonomy Levels 3 and 4 are the ones that will scale without governance failures. Keep the tone practical and direct, not alarmist.
Sources
Filed underOne Metric,