Semantic Layer Architecture for LLM-Powered Analytics
A semantic layer governs what data means, not just how to access it.
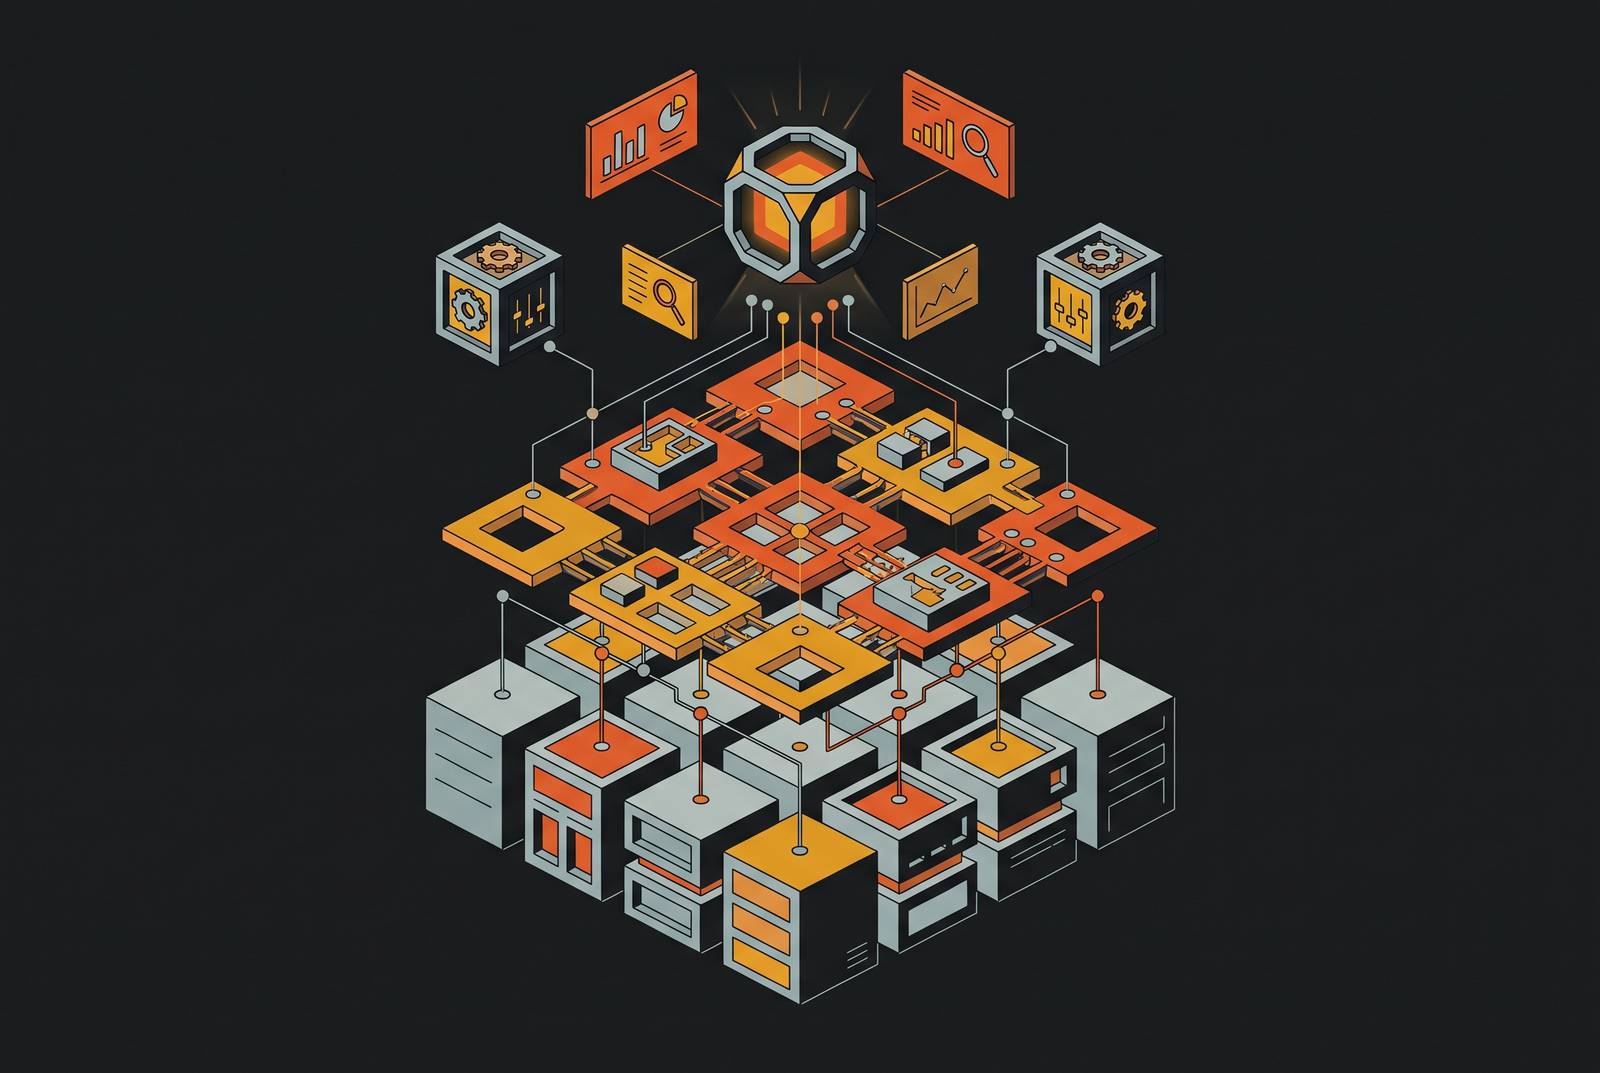
LLM-powered analytics requires an architecture that separates interpreting a question from deciding what its answer means. A semantic layer provides that separation. By placing business definitions, access rules, and pre-calculated metrics outside the model, it turns probabilistic schema guesses into governed answers that deterministic software can execute.
Why LLMs produce wrong analytics answers even when the SQL runs
An LLM reads a column called amount, writes valid SQL, and returns a number without knowing whether refunds should be subtracted, currency normalized, or tax included. Qing Ye’s DABStep ablation documents a further consequence of ungoverned access. The ungoverned agent arms sent 166 mutating statements to the database, while the governed arms sent none.
The same study makes the semantic failure precise. A business code can have a meaning that its column name does not record. A join can depend on a cardinality convention, while a NULL’s meanings can include “applies to everything” and “unknown. The database can execute the resulting query without resolving any of those ambiguities. Successful execution proves that the statement is acceptable to the database, leaving unverified whether the answer matches what the business needs to know.
Michael Rumiantsau and Ivan Fokeev’s 2026 paired benchmark found that three frontier models clustered within a few points of each other without semantic context. A structural description tells the model which tables and columns exist, but not which interpretation the business has agreed to use.
What a semantic layer actually is and what it encodes
Atlan defines a semantic layer as a governed translation layer between raw storage and the tools people and AI agents use to ask questions. It centrally encodes business meaning so that downstream consumers cannot redefine it unilaterally. Its building blocks are measures, dimensions, entities, relationships, and hierarchies. These describe agreed calculations, attributes for filtering, business objects, joins, and drill-down paths. Access controls set which values each consumer may see.
Monthly Active Users provides a concrete example. Without a semantic layer, every BI tool, notebook, and agent rebuilds the joins, filters, and exclusions needed to calculate it. With one, the question becomes a governed lookup. The definition remains declarative, describing what the metric means and making that meaning reusable across queries. Its multi-dimensional structure permits slicing by region or time, while row-level security and column masking apply uniformly.
This is more than shared calculation logic. An agent can query without supervision and route its answer into a downstream workflow, propagating an incorrect interpretation without a human checkpoint. Central definitions therefore need enforceable access policy as well as consistent formulas.
How semantic content — not retrieval scaffolding or model capability — drives accuracy gains
Ye’s study separates semantic knowledge from the machinery that delivers it. Its ablation takes prose out of a frozen data contract but keeps the tool surface, retrieval instructions, table allowlist, and operation rules. Scaffolding without semantic content gives flash and frontier models only small gains, far less than they gain from the content alone. The distinction is central to the architectural argument.
The contract also outperformed equivalent knowledge pasted into a prompt on every model tested. In the contract form, the relevant rule was one lookup away, while the prompt form buried it in a long prompt. The contract gave the correct fee semantics in the vast majority of cases, while the prompt arm did so in only a small fraction.
Compiled expressions established a stronger reliability bound. When the contract’s SQL expressions became views, they gave the right answer on every task they covered. That result is limited to the covered tasks, but it identifies the remaining difficulty as deriving answers from available knowledge. The study’s prescription is “semantics first, scaffolding second, pre-computed macros only where an agent demonstrably fails to derive.”
The architecture that works — LLM selects governed objects, deterministic software executes
The working architecture assigns interpretation to the LLM and execution to deterministic software. The model interprets the question and selects governed semantic objects. Software then resolves joins, formulas, access policy, and SQL generation. The boundary is deliberate and technically significant. The model can choose the relevant metric without receiving authority to redefine its calculation.
The agentic-data-contracts project makes that boundary concrete through a YAML data contract. The artifact contains domain semantics, a forbidden-operations denylist, a table allowlist, domain-level rules, and resource limits. Its semantics describe the business, while its rules constrain the agent’s tools. Together, they define both what a request means and what the agent may do to answer it. The contract is therefore more than documentation placed near a query tool.
Atlan places governance enforcement at query time, before any result returns. Row-level security and column masking apply when the semantic layer intercepts the query. Verification belongs within this architecture too. Snowflake’s Verified Query Repository, Databricks’ trusted assets and benchmarks, Power BI’s verified answers and answer diagnostics, and dbt’s git review and CI pipelines provide human-in-the-loop gates. Their surface forms differ, but each includes a mechanism for controlling what the AI may present as authoritative.
Why MCP connectivity does not substitute for semantic governance
MCP standardizes how context reaches an agent. A server exposing raw schemas still leaves the model to infer business definitions. Settling a disagreement over how to define a conversion event requires a single human-established definition. Without it, connectivity distributes the unresolved ambiguity to more consumers.
MCP’s primitives can support a governed interface when the model already exists behind it. Tools perform actions such as running queries, Resources supply context such as schemas and governed datasets, and Prompts provide reusable workflow templates. These primitives let a server expose both data access and the context required to use it correctly. They do not create metric ownership or agreed formulas themselves.
Protocol improvements address a different engineering problem. The July 2026 MCP specification introduced a stateless core that lets requests reach any server instance behind a plain round-robin load balancer, simplifying horizontal scaling. That change does not introduce semantic governance. Gartner’s February 2026 “Market Guide for Agentic Analytics” warned that by 2028, 60% of agentic analytics projects relying solely on MCP would fail because they lacked a consistent semantic layer.
The specific risks of letting agents touch production databases directly
Without governed definitions, an agent chooses its own joins and filters, so its numbers may differ from those in governed dashboards. On Supabase and Postgres, large scans and aggregations also risk connection-pool exhaustion and degraded response times for live users. These workloads compete with the operational application itself. A well-written prompt does not provide workload isolation.
The safe pattern separates analytics from the production instance. Supabase’s published guidance recommends moving expensive reporting to replicas, materialized views, or external analytics systems. For Postgres teams, the governed agent architecture places an MCP server over a governed copy of the data, keeping production isolated. Isolation protects the operational database, but the analytical copy still requires scoped access rules.
Security must apply to each query. Agents should not have production database credentials embedded in their configuration. Instead, each agent should have a dedicated agent identity that can access only the data it needs, and every tool call should pass through a single policy enforcement point. Attribute-based access control and row-level security restrict returned records, while column masking redacts sensitive fields. A fraud detection agent, for example, can get transaction amounts and timestamps without getting payment card numbers.
Pre-calculated metrics as the correct unit of agent consumption
With pre-calculated, governed metrics, business logic lives upstream in version-controlled code. The agent consumes an agreed result rather than inventing a calculation from raw tables at request time. This removes a derivation step from the model. For high-stakes or high-frequency metrics such as ARR, churn, and CAC, pre-calculation should be the default. On-demand derivation remains a fallback for exploratory or low-stakes questions.
That distinction preserves the study’s caution about unnecessary pre-computation. Metric ownership becomes enforceable through the shared definition. When a calculation changes centrally, downstream human and agent consumers receive the corrected number under a shared interpretation.
The operational expression is a data factory. A shared layer serves human teammates and AI agents from the same pre-calculated definitions, pushing metrics to where work happens instead of requiring each consumer to reconstruct them on demand. The investment can begin with a bounded scope. Atlan’s guidance says to start with 5–20 metrics whose definitions are in dispute and build the first layer in weeks. Establishing that foundation early avoids re-modeling the same definitions as additional consumers arrive.
How open standards are making the semantic layer portable across the agent ecosystem
Open standards are moving semantics beyond individual BI tools. dbt Labs open-sourced MetricFlow, while Snowflake co-founded and led the Open Semantic Interchange initiative as a cross-vendor standard. Atlan states that the standard was finalized in January 2026. Its premise is portable semantic definitions, allowing a metric modeled in one tool to be consumed by another without re-encoding its logic.
For Supabase and Postgres teams, an MCP server can expose pre-modeled metrics, governed datasets, and reusable prompt templates through one endpoint. A new agent framework can use that server and its existing semantic model. In this headless analytics pattern, the governed backend is free of ties to any single front end, and agents and human interfaces use the same shared definitions. Together with Gartner’s warning about MCP-only projects, this shift positions semantic governance as essential infrastructure.
What teams should build first before exposing any agent to their data
Teams should first identify the metrics whose numbers are disputed and assign one owner to each. That owner must be the final arbiter of the definition before modeling begins. Tooling cannot settle an unresolved business disagreement. Starting with disputed metrics targets the questions most likely to produce divergent answers from an ungoverned agent.
For B2B SaaS startups, the initial set should be CAC, LTV, monthly churn, ARR, and gross margin. Teams should model these five as pre-calculated, governed datasets before they add other metrics to the agent’s context. That first model should also enforce access policy. The analytical layer should then be exposed through a governed MCP server, with agents kept away from the production instance.
Verification must precede access by end users. The initial build should include a human-in-the-loop workflow that designates which answers the AI may present as authoritative. This completes the separation of responsibilities established by the architecture. People own the definitions, deterministic software enforces and executes them, and the LLM selects the governed objects needed to answer the question.
Sources
- What Is a Semantic Layer? Types, Tools & AI Grounding
- Which Part of the Context Layer Does the Work? Separating Semantic Content from Retrieval Scaffolding in Text-to-SQL Agents
- Semantic Layers for Reliable LLM-Powered Data Analytics: A Paired Benchmark of Accuracy and Hallucination Across Three Frontier Models