Why Behavioral Segmentation Breaks Without a Canonical User Definition
Establish who counts as one user before building segments, or watch your numbers drift.
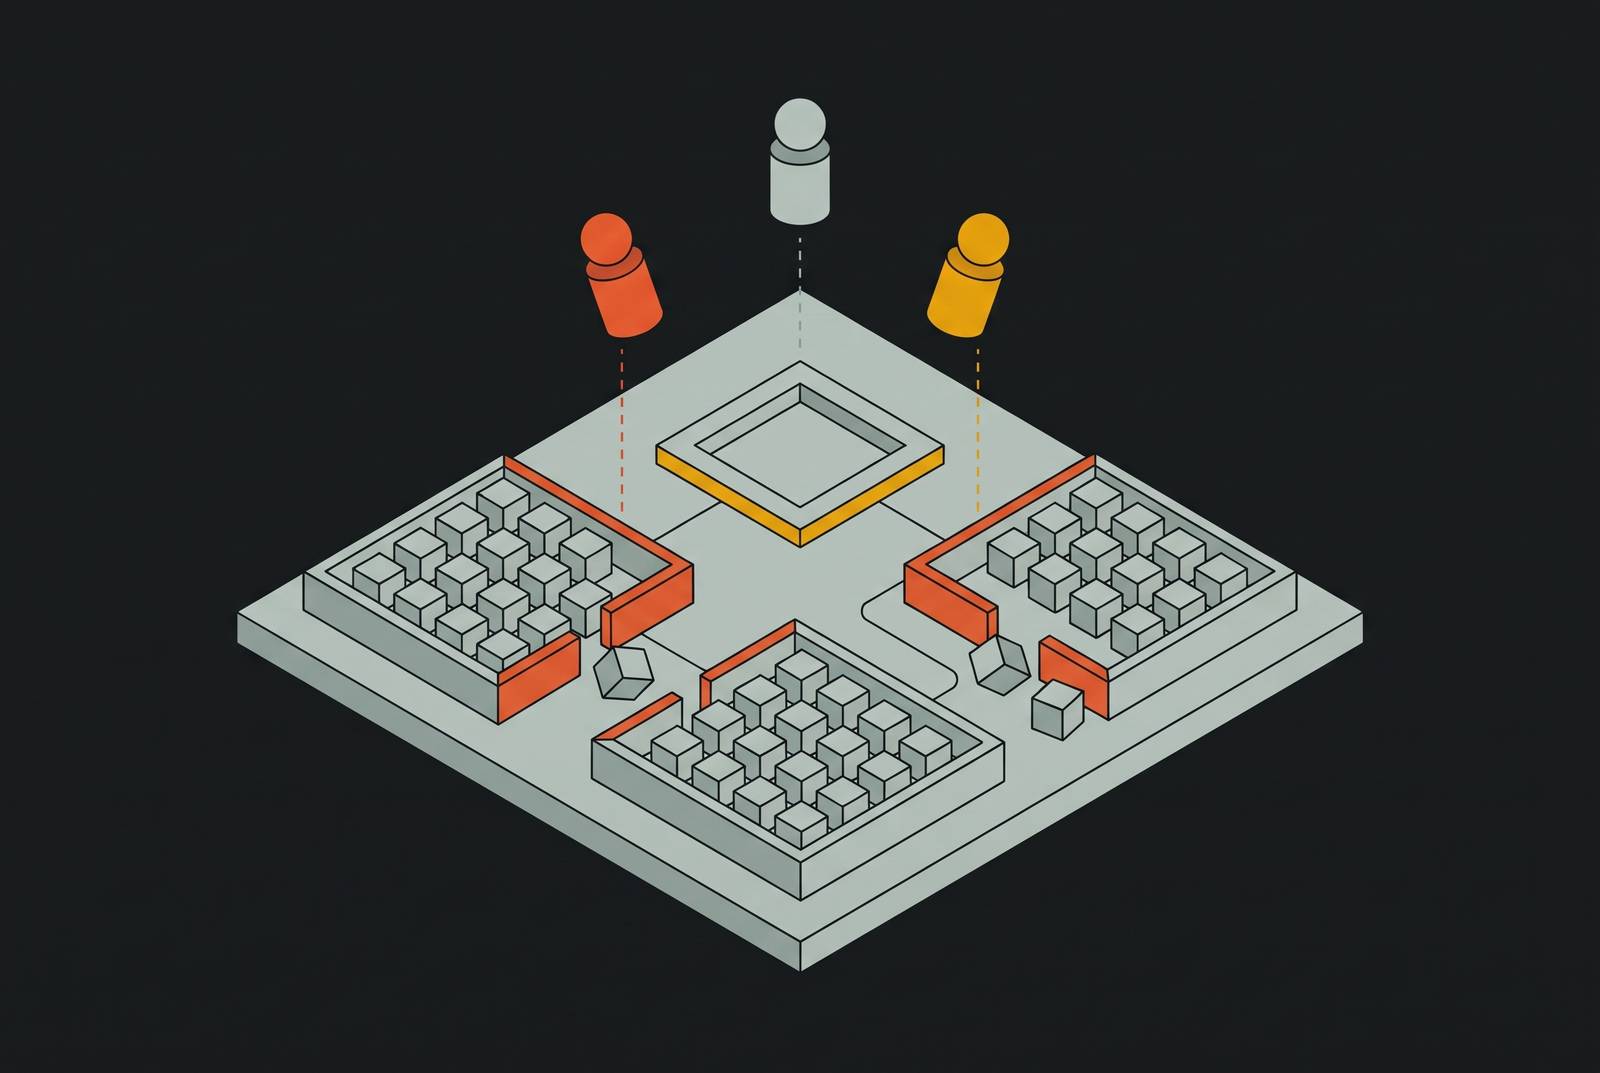
Behavioral segmentation breaks when a team has never agreed on who counts as one user. Better tools and more events cannot settle that question. A canonical user definition, governed across systems and used by every downstream query, is the prerequisite for coherent behavioral signals, stable segments, and trustworthy decisions.
Why behavioral segmentation has an identity problem, not a tool problem
A product team sees segments that look right on Monday and wrong by Thursday. Customer success reports churn numbers that do not match those from sales. The instinct is to question the dashboard, replace the segmentation tool, or collect more events. Yet the break can sit upstream of all three. Each team may be counting a different version of a user.
Segmentation divides a user base into groups based on shared behaviors or attributes. That requires a stable unit of analysis. Logins, feature adoption, and support activity become meaningful together only when they attach to the same user record. Otherwise, a segment can reflect how systems split a person’s behavioral history.
Stitching matches identifiers under rules or probabilities, but it cannot supply an organizational definition that was never established.
What "canonical user definition" means in practice and why it is hard to have one
A canonical user definition is an organization-wide agreement on what constitutes a single user across every system that records behavior. It is not just a database primary key. The same human may appear under a mobile device ID, an email hash in the CRM, an anonymous web session, and a billing customer ID in Stripe. None of those identifiers inherently establishes the relationship among the records. The definition specifies which records belong together and how the organization recognizes that relationship.
Anonymous signup makes the gap easy to see. A person who starts anonymously and later authenticates may appear in two database rows. A query that joins events only on the authenticated user_id can miss the anonymous portion of that person’s history. The query may be valid while its account of the user is incomplete.
Matching technology helps implement the agreement, but introduces choices of its own. Deterministic links provide high certainty where verified identifiers exist, while probabilistic links extend reach at the cost of certainty. Their reliability depends on the verified pairs used to train and validate them. Meanwhile, marketing, product, customer success, and finance maintain tables built for different purposes. Agreement therefore requires organizational work alongside matching.
How the missing definition corrupts every behavioral segment a team builds
DAU and MAU double-count split identities when the same person appears as two active users. Churn calculations can count a person’s continued use after re-registering under a new email as a lost user and a new acquisition. Activation can be undercounted when the qualifying behavior happened anonymously and the query reads only the authenticated record. Each changes the population a team believes it is serving.
The error then propagates into behavioral groups. Active, at-risk, power, new, and churning users require different engagement strategies, but a split identity can place one person in both “new” and “churning.” Customer success may therefore act on contradictory classifications of the same customer. Neither classification has the full history needed to judge how the person behaves.
Segment membership can also drift without a behavioral change. Switching devices, re-registering, or upgrading plans may change which record a query finds. When sales, finance, and product query their separate user tables, their cohort results diverge accordingly. The executive discussion becomes an argument about which number is right, because “which users activated” and “which users churned” have different populations underneath them.
Why the first real analytics question a founder gets asked exposes the gap immediately
Revenue by signup cohort sounds like a straightforward request. To answer it, the team needs to link a signup record to a paying customer. To find which activated accounts churned, the team also needs product behavior, while comparing CAC against usage means joining data from another system. These are everyday business questions, but the joins need an agreement that may be missing from the stack.
A Supabase-native product can have users in Postgres, payments in Stripe, ads in a CRM, and events in a product analytics tool. That is four systems with four user identifiers. Without a canonical bridge, the team has to agree on which records match before it can work out an answer it can defend. The familiar meeting about “which number do we use” exposes this missing agreement.
One dashboard can present a single result without resolving the conflicting definitions beneath it, giving an incomplete calculation the appearance of authority. A warehouse-native tool does not escape this constraint simply because it reads connected sources directly. If its input table contains split identities, it segments those identities faithfully.
What a governed user definition requires before any segmentation layer is added
The prerequisite has three parts. Identity must be resolved across systems, there must be a canonical record with a written account of how it is computed, and every downstream query must use that record as the input the teams have agreed on. Exceptions in individual queries need to be written into the definition so they are out in the open. This is what makes a single source of truth more than a tool choice.
Establishing the record requires choosing deterministic anchors, including hashed email, phone numbers, user IDs, or purpose-built identifiers. Hashed email is useful across digital platforms, but an email address can change over time. Where deterministic linkage is unavailable, probabilistic matching can extend coverage using verified links to anchor and validate the model. Even with matching confidence, the team has to decide what the record it creates stands for.
That decision needs shared ownership. Marketing, sales, RevOps, and engineering each control part of the data, so governance must connect their definitions as well as their identifiers. For a Supabase team, anonymous and authenticated rows illustrate the required order. The team must establish that they represent one user before selecting columns for a cohort query. Otherwise, an approved computation can remain internally consistent while omitting part of the user’s history, and downstream machine learning models inherit the same fragmentation.
How the segmentation tools on the market assume resolved identity and what that means for tool selection
The useful buying question is architectural. Which option keeps the canonical user definition closest to every query that uses it? GA4, Mixpanel, Amplitude, Pendo, and Mitzu offer different segmentation capabilities, but none can decide what an ambiguous organizational schema means. Their interfaces and data models become relevant after that definition is established.
GA4 uses vendor-managed data, and a segment can have no more than four conditions. It is suited to top-of-funnel analysis, with less depth for product-level behavioral work. Mixpanel provides flexible real-time cohorts through a vendor-managed data model, with ownership and portability constraints. Teams need to plan events carefully because a poor setup at the start limits how much value they get over time. Amplitude provides robust behavioral and predictive cohorting with vendor-managed data, a steeper learning curve, and some advanced features behind paid access.
Pendo focuses on in-app behavioral segmentation through a no-code interface. Its native retention cohort analysis includes retroactive historical data, although deeper cross-tool or warehouse-level cohort work may require external tooling. Mitzu is warehouse-native and grounded in a semantic layer, with one hundred percent customer-owned data and unlimited filters through SQL or a visual builder. It works well for high-volume datasets and data-driven organizations, but they need to have data infrastructure in place.
The identity consequence follows from where computation happens. In a vendor-managed model, the team cannot perform its own schema-level resolution inside the vendor’s store, so the canonical definition needs to be applied before events are sent. A warehouse-native tool can read straight from the governed record, so its segments use the warehouse-level resolution already in place. That favors the pattern when control of the canonical record is the deciding requirement.
Why AI agents make the canonical user definition a safety requirement, not just an analytics preference
Two agents can treat the same human as two different customers. An at-risk query may flag the person twice, or classify one record as healthy while another triggers outreach. The agents can take actions that clash even when both stay within their permissions. The defect lies in the shared grounding even if both agents reason correctly.
Agent-to-agent workflows add a separate policy risk. Data can be processed or combined in prohibited ways even when individual agents operate within their stated permissions. For example, a reporting agent might ingest unmasked data from an intermediate output. Access controls therefore need to govern both each agent’s immediate task and the data available through the workflow.
Agents should use least-privilege, just-in-time access to pre-modeled data. An agent’s access should be limited to the data its task requires. Direct access to production Postgres, including a Supabase-managed database, exposes analytical work to RLS friction, pooler limits, and unresolved OLTP identities. If that access omits anonymous history, the agent receives a systematically incomplete account of engagement. Better reasoning cannot bring back records that were never connected in the agent’s input.
How a governed semantic layer makes the canonical user definition available to both humans and agents
A governed semantic layer turns the user agreement into queryable datasets. It defines metrics, entities, relationships, and governance policies so that dashboards and agents consume the same modeled record. The useful analytical unit is then a prepared dataset, rather than a fresh interpretation of production tables for every question. This separates the meaning of the data from the interface used to request it.
Model Context Protocol, launched by Anthropic in November 2024, gives AI systems a standard way to access external data. It separates the AI client, the MCP server’s connector logic, and the resource. Transport is not context, however. MCP provides access, while the semantic layer supplies the definitions that make the returned data meaningful. A working connector cannot correct a fragmented user definition.
Pre-modeled Parquet datasets queried through DuckDB let agents work without touching the production database. If canonical identity has already been resolved in those datasets, consumers do not have to reconstruct it from ambiguous OLTP rows. The condition is essential. Changing the storage format alone does not resolve identity.
For Supabase and Postgres teams, this architecture also keeps heavy analytical work apart from the work of serving the application. Full-table cohort scans and window functions over event logs reach the limits on connections and compute sooner than the application’s usual traffic does. Defining metrics over a governed analytical dataset allows dashboards, agents, and APIs to use that layer instead. With Headless analytics, the definition is available through MCP or API without being tied to any single front end.
What to do first if your team's behavioral segments are built on unresolved identity today
The first step is an audit. Find every place where a user is defined in the product database, CRM, billing system, and analytics tool. Flag disagreements in meaning and differences in primary identifiers. Then check whether each operating metric has one approved computation path or several versions that compete with each other. This reveals the definition work that must precede another segmentation layer.
For Supabase teams, the immediate check is whether anonymous signups and authenticated users resolve into a single canonical row before cohort queries run. A user_id join that excludes anonymous sessions can undercount activation and miscount churn. Narrow the metrics while correcting that foundation. Pre-product-market-fit teams should track a small number of operating metrics that expose friction, rather than add segments to numbers whose populations remain unresolved.
Establish the canonical record before choosing the segmentation tool. Teams without a dedicated data engineer can obtain the layer from a governed data partner. The deliverable is an agreed definition and approved computation path that both people and agents can use.
Once that governed layer exists, calculate metrics ahead of time and push them to a team messaging platform, inbox, or the weekly review. Decisions should not hinge on who remembers to open an analytics tool. With identity settled before computation, those reviews can focus on what changed in user behavior and what action follows, rather than reopening the argument about who was counted.